In this post, we review two important facts of Dirichlet distribution. The basic setting used here as follows. Suppose we have a discrete space
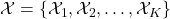
. These are
outcomes can be observed from the “random experiments”. Suppose we have
observations
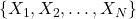
that are distributed according to a Multinomial distribution
where
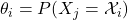
. After placing a Dirichlet distribution
on
, we are interested in the following two questions:
- What is the posterior distribution
? - What is the predictive distribution
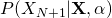
?
Posterior Distribution
We can steadily derive the posterior distribution as below:
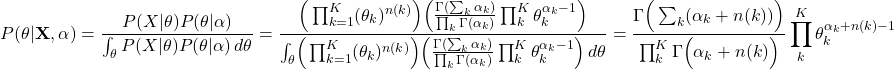
![Rendered by QuickLaTeX.com \[ P(\theta | \mathbf{X}, \alpha) = \frac{P(X|\theta)P(\theta|\alpha)}{\int_{\theta} P(X|\theta)P(\theta|\alpha) \, d\theta} \\ = \frac{\Bigr( \prod_{k=1}^{K} (\theta_{k})^{n(k)} \Bigl) \Bigr( \frac{\Gamma(\sum_{k} \alpha_{k})}{\prod_{k} \Gamma(\alpha_{k})} \prod_{k}^{K} \theta_{k}^{\alpha_{k} - 1} \Bigl) }{\int_{\theta} \Bigr( \prod_{k=1}^{K} (\theta_{k})^{n(k)} \Bigl) \Bigr( \frac{\Gamma(\sum_{k} \alpha_{k})}{\prod_{k} \Gamma(\alpha_{k})} \prod_{k}^{K} \theta_{k}^{\alpha_{k} - 1} \Bigl) \, d\theta } \\ = \frac{\Gamma \Bigr( \sum_{k} ( \alpha_{k} + n(k) ) \Bigl)}{\prod_{k}^{K} \Gamma \Bigr( \alpha_{k} + n(k) \Bigl)} \prod_{k}^{K} \theta_{k}^{\alpha_{k} + n(k) -1 }\]](https://www.hongliangjie.com/wp-content/ql-cache/quicklatex.com-621b8e2cca88ade20bda4684ff4d69ca_l3.png)
where
is the number of times outcome
appear in the data. Therefore, the posterior distribution is indeed a Dirichlet distribution
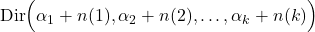
. If we only have one observation
, this posterior distribution is simply
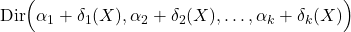
where
is
only if
takes the value of outcome
. This notation can also extend to the general case that the posterior distribution is
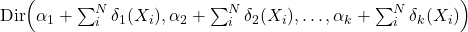
.
Predictive Distribution
By using the posterior distribution derived above, we can have the predictive distribution as follows:
(1) ![Rendered by QuickLaTeX.com \begin{eqnarray*} P(X_{N+1} &=& \mathcal{X}_{i} | \mathbf{X}, \alpha) = \int_{\theta} P(X_{N+1} = \mathcal{X}_{i} | \theta) P(\theta | \mathbf{X}, \alpha) \, d\theta \\ &=& \int_{\theta} \theta_{i} \Biggr[ \frac{\Gamma \Bigr( \sum_{k} ( \alpha_{k} + n(k) ) \Bigl)}{\prod_{k}^{K} \Gamma \Bigr( \alpha_{k} + n(k) \Bigl)} \prod_{k}^{K} \theta_{k}^{\alpha_{k} + n(k) -1 } \Biggl] \, d\theta \\ &=& \mathbb{E}[\theta_{i}] \\ &=& \frac{\alpha_{i} + n(i)}{\sum_{k} \Bigr( \alpha_{k} + n(k) \Bigl)} = \frac{\alpha_{i} + \sum_{j}^{N} \delta_{i}(X_{j})}{\sum_{k} \alpha_{k} + N } \end{eqnarray*}](https://www.hongliangjie.com/wp-content/ql-cache/quicklatex.com-622550f806ce28e9a42e07109eacd820_l3.png)
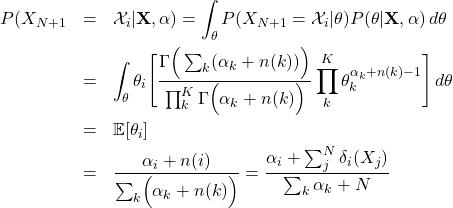
where the second last line is derived by observing that the posterior distribution is a Dirichlet distribution and the expression is essentially an expectation under that distribution. Note, the final line of the equation can be re-written into:
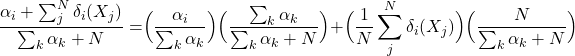
![Rendered by QuickLaTeX.com \[ \frac{\alpha_{i} + \sum_{j}^{N} \delta_{i}(X_{j})}{\sum_{k} \alpha_{k} + N } = \Bigr( \frac{\alpha_{i}}{\sum_{k} \alpha_{k}} \Bigl) \Bigr( \frac{\sum_{k} \alpha_{k}}{\sum_{k} \alpha_{k} + N} \Bigl) + \Bigr( \frac{1}{N} \sum_{j}^{N} \delta_{i}(X_{j}) \Bigl) \Bigr( \frac{N}{\sum_{k}\alpha_{k} + N }\Bigl) \]](https://www.hongliangjie.com/wp-content/ql-cache/quicklatex.com-6adc368f84b874dea14ea00187ba1f90_l3.png)
It is the weighted summation of prior mean of
and the MLE of
. There is one extreme case for predictive distribution, which is that there is no data points before. By using the equation we derive above, we have:
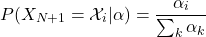
![]()
These two distributions are heavily used in Dirichlet/Multinomial Bayesian modeling and also are milestones for understanding Dirichlet Process.