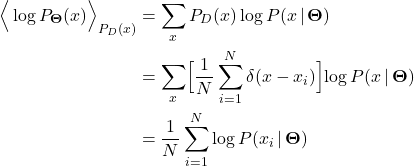Maximum Likelihood as Minimize KL-Divergence 8
When I study Product of Experts and Restricted Boltzmann Machine recently, I have found a very interesting technical point to be demonstrated. That is maximum likelihood estimation can be viewed as a process to minimize a KL-Divergence between two distributions.
We start from a simple notation. Let  be the distribution for generating each data point
 . We can define the model parameter distribution as:
(1) 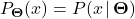
(2) 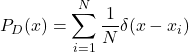
 is the Dirac delta function. We can verify that this is a valid distribution by summing over all
 :
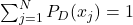 . By using this empirical data distribution, we wish to calculate the following KL divergence:
(3) 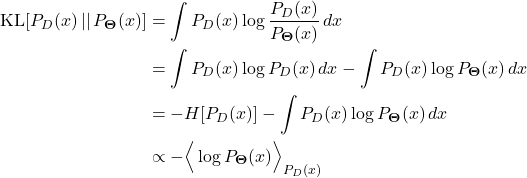
 , which has nothing to do with parameters
 and
 represents the expectation over
 . If we minimize the left hand side KL divergence, it is equivalent to minimize the negative expectation on the right hand side. This expectation is indeed:
(4)