When I study Product of Experts and Restricted Boltzmann Machine recently, I have found a very interesting technical point to be demonstrated. That is maximum likelihood estimation can be viewed as a process to minimize a KL-Divergence between two distributions.
We start from a simple notation. Let  be the distribution for generating each data point
 . We can define the model parameter distribution as:
(1) 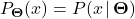
(2) 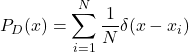
 is the Dirac delta function. We can verify that this is a valid distribution by summing over all
 :
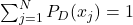 . By using this empirical data distribution, we wish to calculate the following KL divergence:
(3) 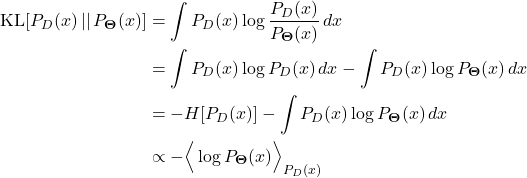
 , which has nothing to do with parameters
 and
 represents the expectation over
 . If we minimize the left hand side KL divergence, it is equivalent to minimize the negative expectation on the right hand side. This expectation is indeed:
(4) 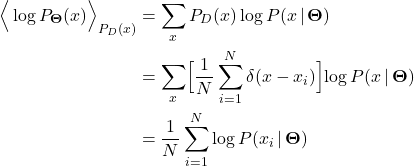
Hi LiangJie,
This is a really cool result. Where did you come across this?
I had the feeling that something like this holds but wasn’t sure how to go about it.
I’d appreciate it if you’ve got any more info regarding this.
Cheers,
Dror
Thanks, Dror.
In fact, I would say that this is probably a standard result. For example, someone else has a similar blog post: http://quantivity.wordpress.com/2011/05/23/why-minimize-negative-log-likelihood/
Hi LiangJie. This is nice but I think that KL(P ||Q) only exists when the radon nikodym derivative of P exists with respect to Q, ie P is absolutely continuous with respect to Q. Otherwise you get into difficulties integrating over the logarithm of zero. In your case, the expression log(P_D(x)) may not make mathematical sense. I don’t think you can take logarithms of the Dirac Delta function, since this is not a ‘function’ as such, but a distribution.
I think you left a integral mark at (5). Also, how do you get (6) from (5)
Hi Luyao,
Equation (5) does not leave an integral as the expectation is over all data points. So it is a summation. (But “dx” should be removed and I’m going to revise that.) Equation (6) directly comes from the definition of the empirical data distribution.
I think there should be an integral, you should just replace PD(x) with its definition. Now, it is not even a probability.
OK. I do miss a summation there. Now, it’s clear. The integral is the summation here as the expectation is taken with respect to a discrete distribution, empirical data distribution. The last line is from the change from x to x_i.
The outer summation is sum over all possible x while the inner summation is over all data instances. The outer summation is gone as the change of x to x_i.
Thanks for pointing out this.
I was solving a problem from Duda and Hart (also in Bishop). Minimizing the KL distance is equivalent to computing an MLE estimate. Aside from the Dirac-Delta function (which is quite cool), my interpretation is that we can view it as a sort of Monte Carlo estimate where we average over N (see Doucet’s notes – which also contains Dirac Delta function – http://www.stats.ox.ac.uk/~doucet/doucet_defreitas_gordon_smcbookintro.pdf)from points taken from the distribution we have data from.